Demos








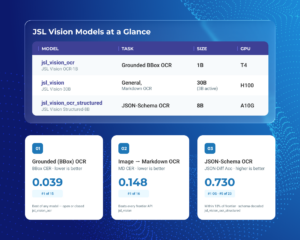
For clinical search and RAG pipelines, OCR quality determines how reliably you can retrieve information from scanned documents. In John Snow Labs’ FUNSD plain-text OCR benchmark, the self-hosted JSL Vision model recorded a character error rate of 0.148, compared with 0.155 for Grok-4 and 0.167 for Gemini 2.5 Pro. These results support evaluating an OCR pipeline that keeps documents inside your environment.
Our grounded OCR benchmark evaluated text extraction with bounding-box coordinates. This article evaluates full-page text in reading order, the output you need for document indexing and downstream text processing.
The comparison covers 16 models. API evaluations used 50 FUNSD pages, while locally evaluated VLMs used 10 because of GPU constraints. Read the scores alongside those sample sizes.
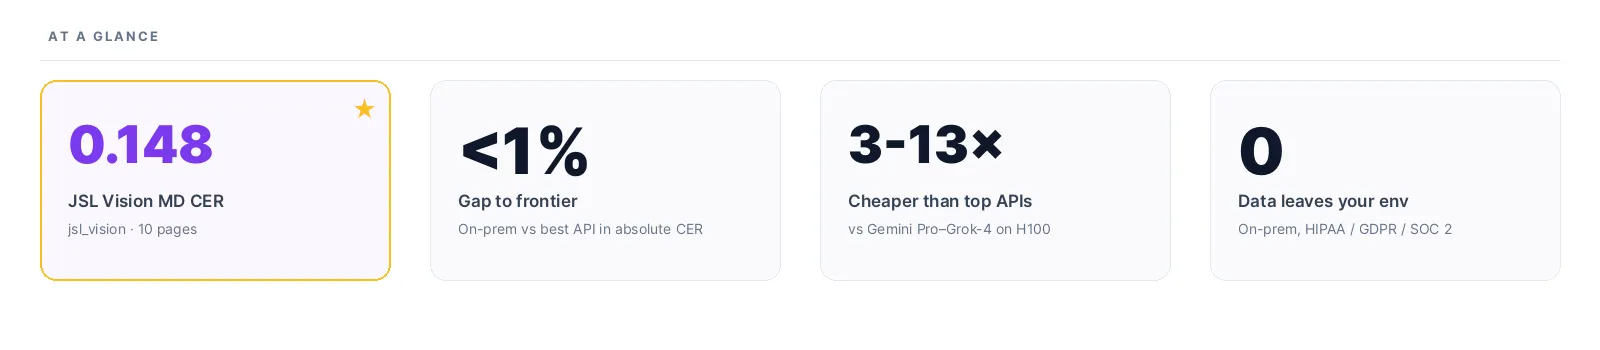
The CER gap is 0.0073 (0.73 percentage points), with different evaluation sample sizes. The approximate 3–13× cost comparison uses the historical $6.76 H100 estimate explained in table note 2 and excludes software licensing and operations. Local inference supports data control; compliance depends on the complete deployment.
What “markdown OCR” looks like
Plain-text OCR converts a document image into text arranged in reading order. Markdown output can retain headings and other formatting for downstream processing.
The example below shows the input document on the left and JSL Vision’s output on the right.
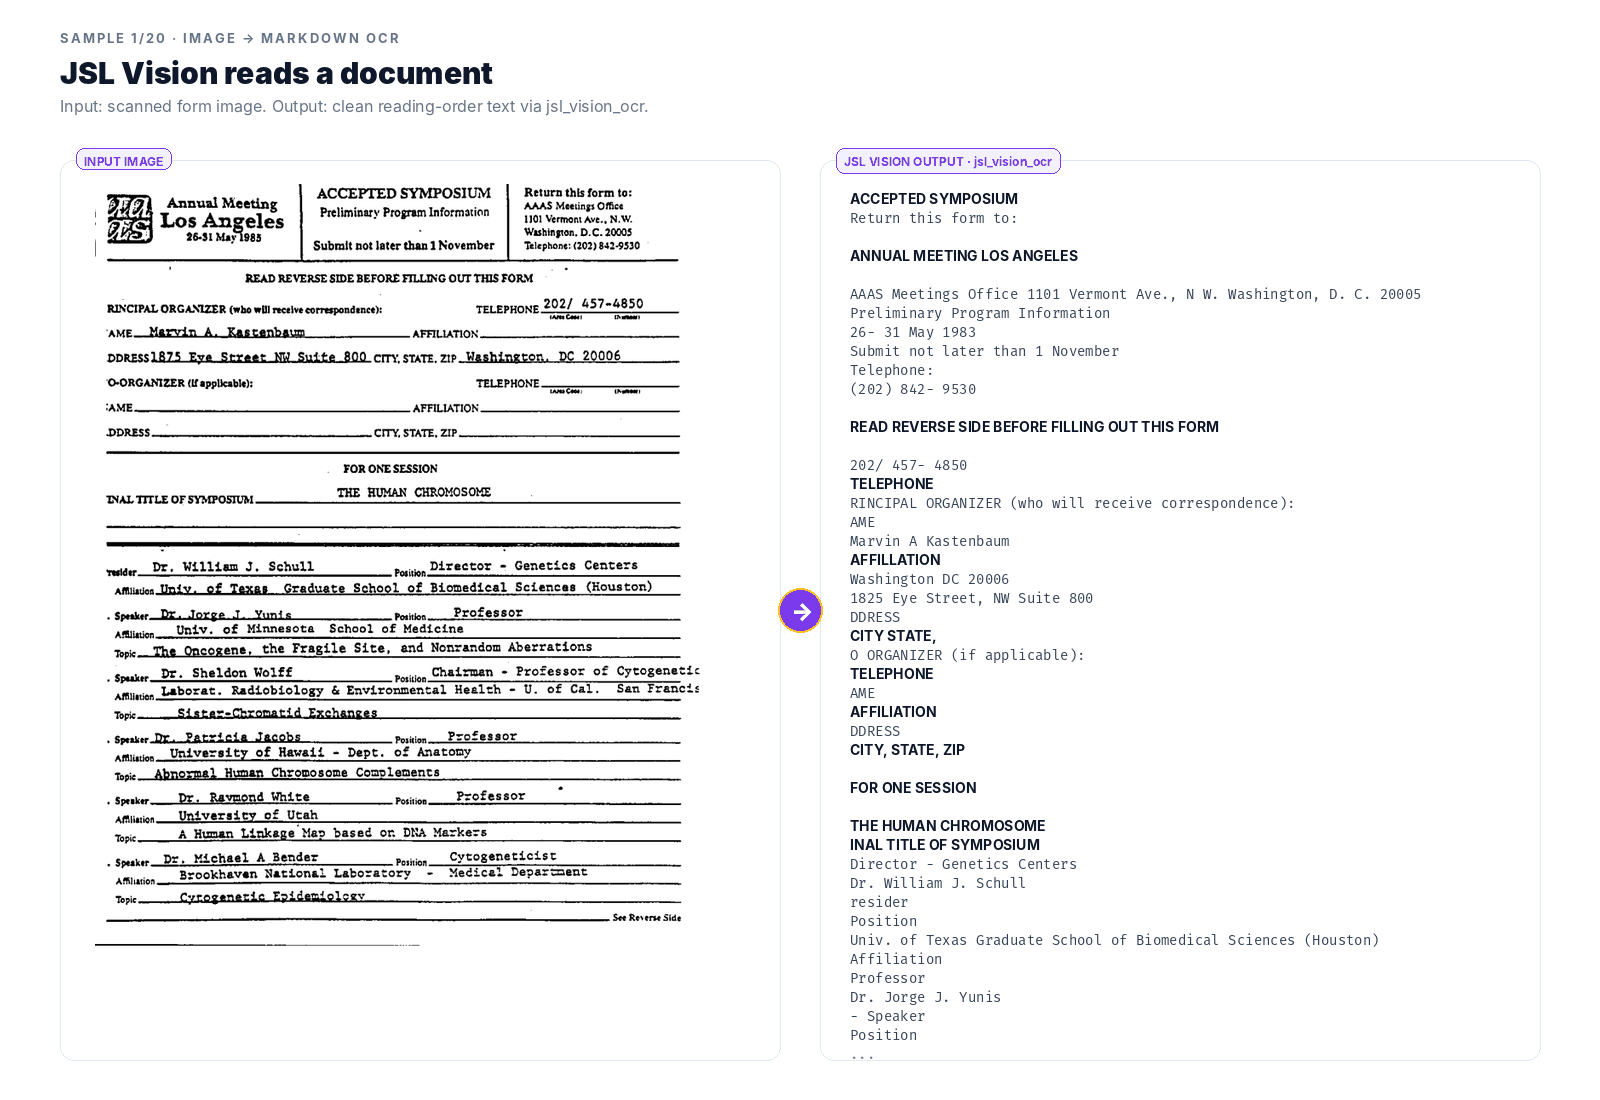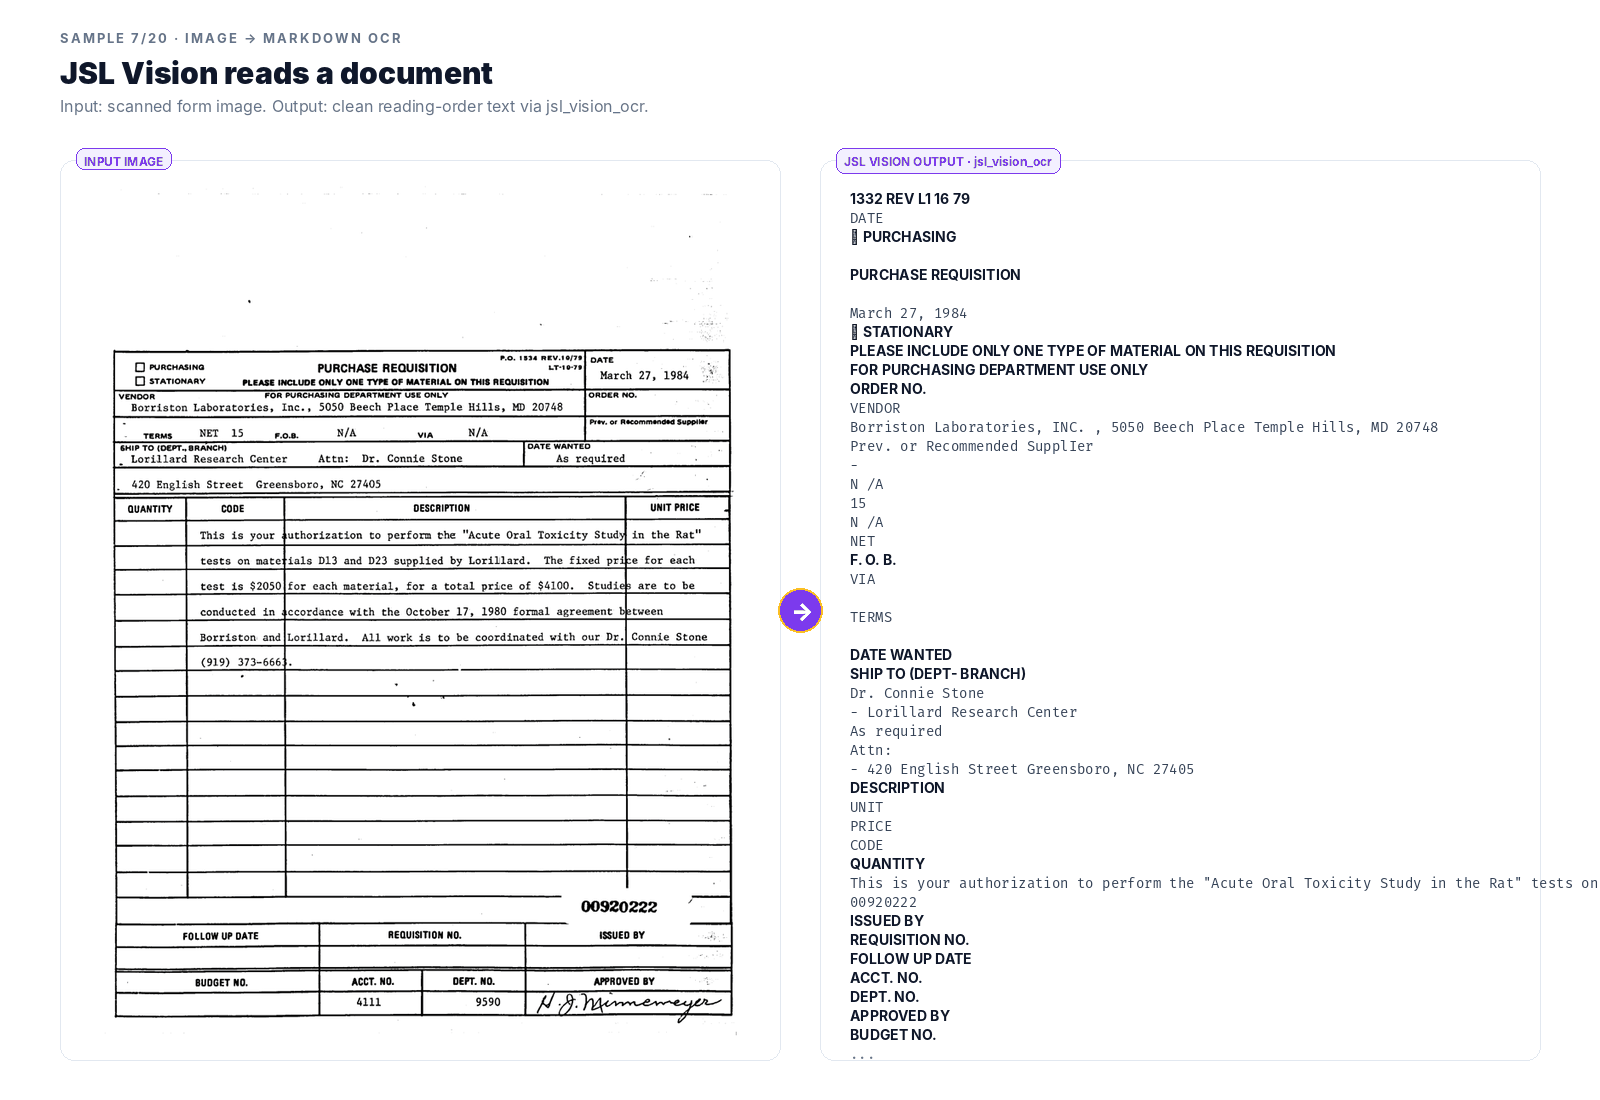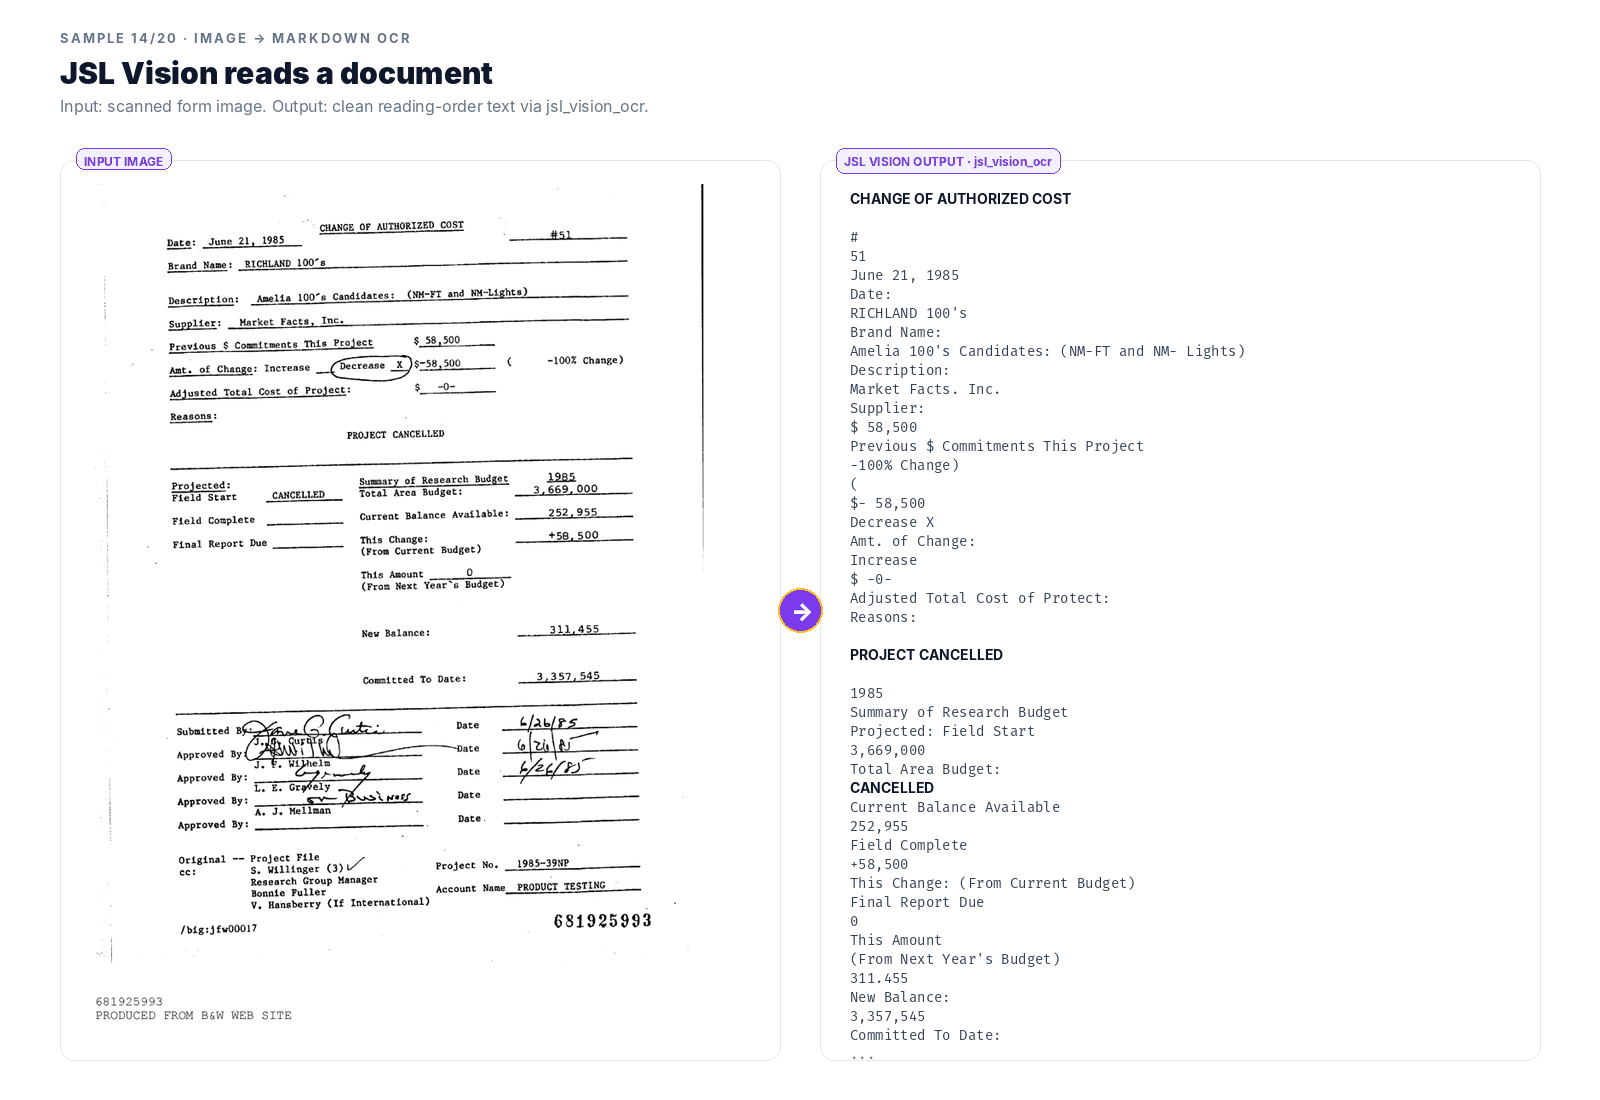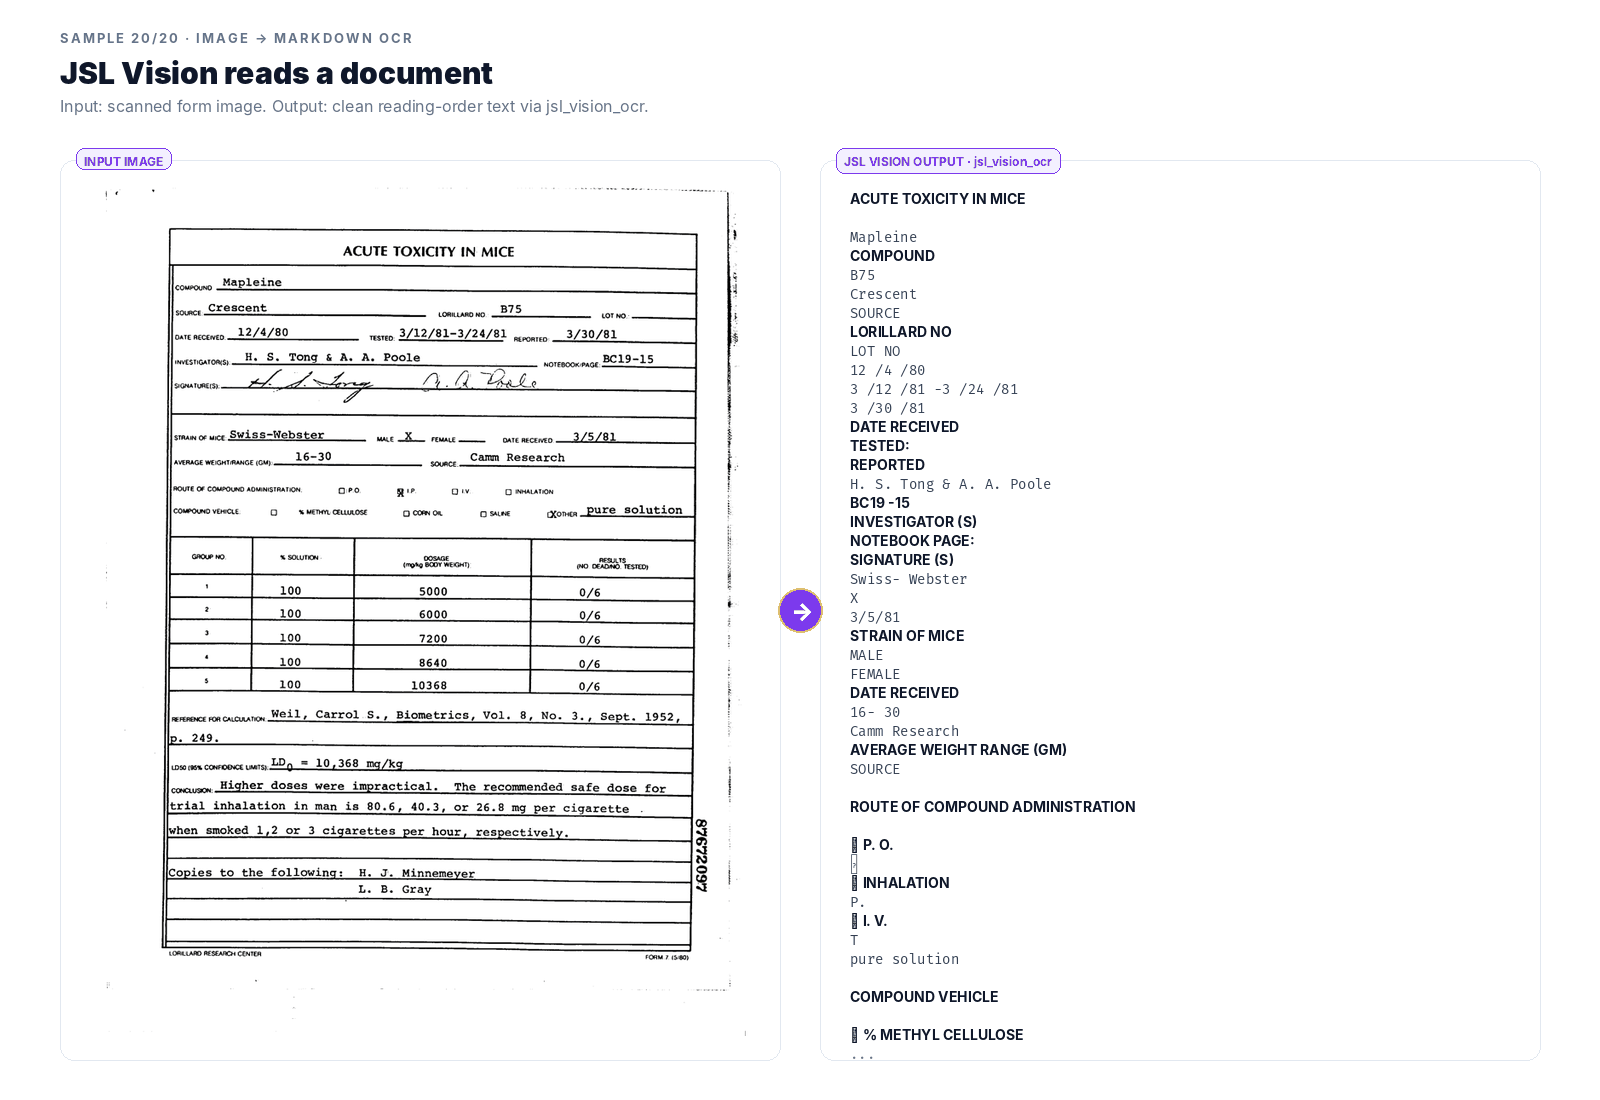
For this benchmark, we normalized the output before scoring. Bounding-box coordinates and JSON field extraction were evaluated separately in the other articles in this series.
How did we measure plain-text OCR?
- Dataset: FUNSD training pages, 50 pages for API-served models and 10 pages for locally evaluated VLMs (GPU-constrained, see methodology)
- Metric: character-level CER via
jiwer.cer()on full-page text - Ground truth: word-level FUNSD annotations reassembled into line-level reading order (top-left → bottom-right), lowercased, whitespace-normalized
- Predictions: preprocessed identically (strip markdown tables, collapse whitespace, lowercase) before scoring
CER reflects differences in transcription and reading order. On forms, a different ordering of correctly recognized fields can increase the score.
Which model leads on plain-text OCR?
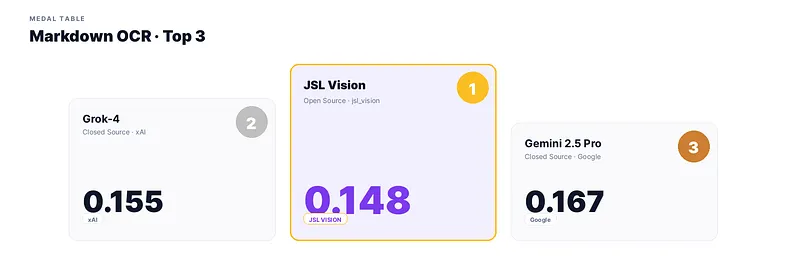
JSL Vision (jsl_vision) recorded the lowest CER in the published comparison at 0.148. Grok-4 followed at 0.155, and Gemini 2.5 Pro scored 0.167.
The difference between JSL Vision and Grok-4 is 0.007 CER, or 0.7 percentage points. The top three scores span 0.019. These are descriptive results from the evaluated samples; the different page counts limit conclusions about how the models compare across other documents.
How all 16 models compare
The published leaderboard shows that self-hosted OCR can achieve a CER comparable to frontier APIs on this FUNSD task. JSL Vision’s recorded CER was approximately 4.5% lower than Grok-4’s.
GPT-5.2
GPT-5.2 scored 0.271 CER, ranking 15th among the 16 models shown. Its result illustrates why you should evaluate a model on your document extraction task before choosing it for an OCR pipeline.
Grok-4
Grok-4 ranked second on plain-text OCR at 0.155 CER. Its result on the separate grounded OCR benchmark was 0.582 BBox CER. Evaluate text recognition and spatial grounding separately when your workflow needs coordinates for redaction or field localization.
Sub-10B open-source models
Qwen3-VL-8B recorded 0.222 CER, compared with 0.227 for Qwen3-VL-235B and 0.271 for GPT-5.2. The 8B result supports including smaller models in your evaluation when deployment resources are constrained. Its evaluation used 10 pages, compared with 50 for the two API-served models.
| Model (historical article label) | Parameters | Pages | Plain-text CER ↓ | Mean seconds / page | Archived cost / 1,000 docs (USD) |
|---|---|---|---|---|---|
| JSL Vision¹ | 30B | 10 | 0.148 | 2.53 | $6.76² |
| Grok-4 | Not stated | 50 | 0.1553 | 15.57 | $86.70 |
| Gemini 2.5 Pro | Not stated | 50 | 0.1667 | 42.73 | $18.86 |
| Claude Opus 4.5 | Not stated | 50 | 0.1689 | 13.00 | $13.07 |
| Llama-4-Maverick | Approximately 400B³ | 50 | 0.1728 | 3.24 | — |
| Claude Sonnet 4.5 | Not stated | 50 | 0.1898 | 16.33 | $7.78 |
| Gemini 2.5 Flash | Not stated | 50 | 0.2069 | 4.81 | — |
| Qwen3-VL-8B | 8B | 10 | 0.222 | 3.66 | — |
| Qwen3-VL-235B | 235B | 50 | 0.227 | 20.90 | — |
| RolmOCR¹ | 7B | 10 | 0.230 | 3.07 | — |
| Chandra OCR 2 | 5B | 10 | 0.234⁴ | — | — |
| Pixtral-Large | Not stated | 50 | 0.2395 | 7.38 | — |
| Nanonets-OCR2-3B | 3B | 10 | 0.263 | 2.65 | — |
| JSL Vision Structured¹ | 7B | 10 | 0.268 | — | — |
| GPT-5.2 | Not stated | 50 | 0.271 | 10.38 | $10.24 |
| Sonar Pro | Not stated | 50 | 0.4394 | 7.71 | — |
— indicates an unavailable verified value. Costs are historical estimates, not current prices. API timings include service response time; local timings measure inference.
¹ Model names follow the original benchmark’s labels.
² The $6.76 estimate uses a reported 9.74 seconds per page at $2.50 per H100 hour. Its underlying timing run was not recovered. It does not correspond to the archived 2.53-second mean shown in this table.
³ Approximately 400B is the parameter count reported in the original article.
⁴ The published Chandra CER of 0.234 could not be verified from the recovered results.
Local CERs retain the archived published values. Re-scoring cached predictions yielded 0.147 and 0.229 for the rows originally reported as 0.148 and 0.230, respectively.
How much does plain-text OCR cost?
Cost comparisons need to distinguish API charges from self-hosted compute estimates. For a self-hosted model, the estimate depends on hardware price and processing time. Your production budget also includes software licensing and operating the service.
The recovered historical cost comparison reports $18.86 per 1,000 documents for Gemini 2.5 Pro and $86.70 for Grok-4. These are archived estimates, not current prices or itemized charges for the exact evaluation pages.
The separate grounded OCR benchmark estimates $0.56 per 1,000 documents for JSL Vision OCR (jsl_vision_ocr) on a T4. That figure belongs to a different model and task from the 30B flagship’s plain-text CER result.
If your pipeline also requires structured fields, review the schema-constrained OCR benchmark. Plain-text CER alone does not measure schema extraction quality.
How fast is each model per page?
For batch ingestion, processing time determines how quickly you can clear a document backlog. For interactive workflows, it determines how long you wait for extracted text.
The archived plain-text API runs averaged 3.24 seconds per page for Llama-4-Maverick, 4.81 for Gemini 2.5 Flash, and 7.38 for Pixtral-Large. The corresponding local runs averaged 2.65 seconds for Nanonets-OCR2-3B and 3.66 for Qwen3-VL-8B. API response time and local inference time reflect different serving conditions.
How do GPU and CPU deployments compare?
We compared OCR models on an NVIDIA H100 and a c5.2xlarge CPU instance with 8 vCPUs. The hardware charts label GPU precision as bfloat16 and CPU precision as float32, using the same prompts and 5 FUNSD pages. JSL Vision OCR’s separate vLLM configuration is discussed below.
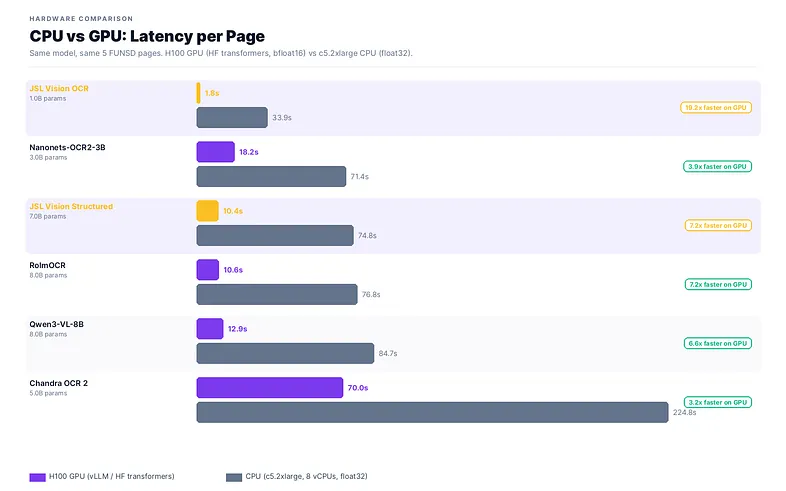
GPU processing was approximately 2–7× faster per page across the tested models, with a maximum reported speedup of 7.2× for models in the 7–8B range.
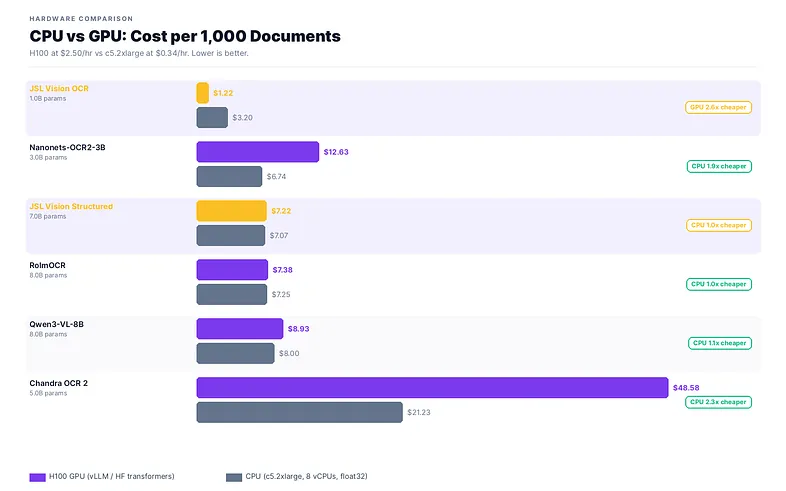
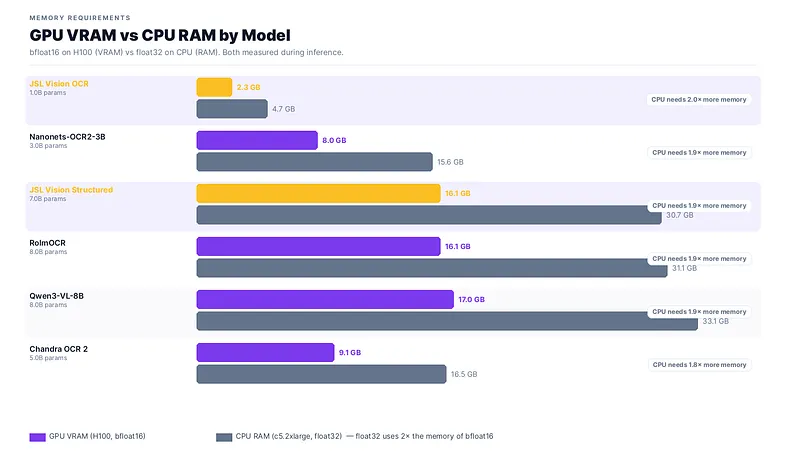
At the benchmark’s hourly prices of $0.34 for CPU and $2.50 for H100, CPU compute cost per document was lower across the configurations tested with Transformers. For JSL Vision Structured and RolmOCR, the CPU and GPU estimates differed by about 2%. Qwen3-VL-8B’s GPU estimate was about 12% higher than its CPU estimate.
The separate JSL Vision OCR configuration served through vLLM was reported at $1.22 per 1,000 documents on H100. Treat this as a comparison of hardware and serving configurations: vLLM introduces an additional difference from the Transformers baseline.
How does on-premises OCR support healthcare workflows?
JSL Vision supports deployment inside your environment through Docker or Amazon SageMaker. The approximately 1B JSL Vision OCR model supports a single-T4 configuration, while the 30B flagship was evaluated on an H100.
Local inference keeps document processing within your infrastructure and gives you control over access and retention. These deployment options support regulatory-grade healthcare AI workflows. Compliance also depends on how you configure and operate the complete system.
For reproducible processing, pin the model version and inference configuration, then validate repeatability in your deployment environment. Supported inputs include PDF, PNG, and JPG, with documents converted to images for inference.
How we ran the benchmark
- Dataset: FUNSD. Reading order via line-level reassembly of word-level FUNSD annotations.
- Metric:
jiwer.cer(gt, pred)at the corpus level, after consistent preprocessing (lowercase, strip markdown separators, collapse whitespace). - Closed-source models: OpenRouter
temperature=0,max_tokens=8192. - Open-source models: vLLM v0.17.1, H100, f16 precision.
- Sample sizes: API-served models were evaluated on 50 pages. Locally evaluated VLMs used 10 pages because of GPU constraints. The unequal sample sizes limit direct comparison; the reported differences do not establish statistical significance.
- Outliers: Ministral-14B produced a 34× length-explosion gen-loop on one page (63 k chars vs 1.8 k GT) that inflated its corpus CER to 1.63 with median page CER of 0.28. It is omitted from the leaderboard; the gen-loop behavior is real and worth knowing about for production deployments.
Frequently asked questions
What does plain-text OCR extract?
Plain-text OCR extracts document text in reading order. It supports document indexing and downstream text processing. Workflows that require word coordinates should evaluate grounded OCR separately.
Which model recorded the lowest plain-text CER?
JSL Vision (jsl_vision) recorded 0.148 CER in the published FUNSD comparison. Grok-4 scored 0.155, and Gemini 2.5 Pro scored 0.167. The evaluations used different sample sizes.
How was character error rate calculated?
The benchmark used corpus-level jiwer.cer() after normalizing reference text and predictions. Normalization included lowercasing and collapsing whitespace. CER penalizes differences in both recognized characters and reading order.
How many pages were evaluated?
API evaluations used 50 FUNSD training pages. Locally evaluated VLMs used 10 pages because of GPU constraints. The separate CPU/GPU comparison used 5 pages.
Are JSL Vision and JSL Vision OCR the same model?
JSL Vision (jsl_vision) is the 30B-class flagship evaluated for plain-text OCR. JSL Vision OCR (jsl_vision_ocr) is the approximately 1B model evaluated for grounded OCR in Part 1. Their scores and hardware cost estimates describe different configurations.
Does a GPU always reduce OCR compute cost?
The H100 processed pages faster than the CPU configurations in the hardware comparison. At the hourly prices used, CPU compute cost per document was lower for the Transformers configurations tested. Hardware choice and serving software both affect the result.
Can document processing stay inside my environment?
JSL Vision supports deployment inside your infrastructure through Docker or Amazon SageMaker. Local inference keeps document processing within that environment. Validate the complete pipeline against your organization’s security and governance requirements.
What’s next
This is the second article in a three-part OCR benchmark series:
- Grounded OCR on FUNSD
- Plain-text OCR on FUNSD, covered here
- Schema-constrained OCR on OmniOCR
JSL Vision recorded the lowest plain-text CER in this comparison, with a 0.007 difference from the strongest API result. The findings support evaluating self-hosted OCR alongside APIs, using your own documents and deployment requirements.
Schedule a demo to evaluate JSL Vision on your document processing workflow.